Templates
Vision Inference Service
Batched, queued detection serving that holds up under load.
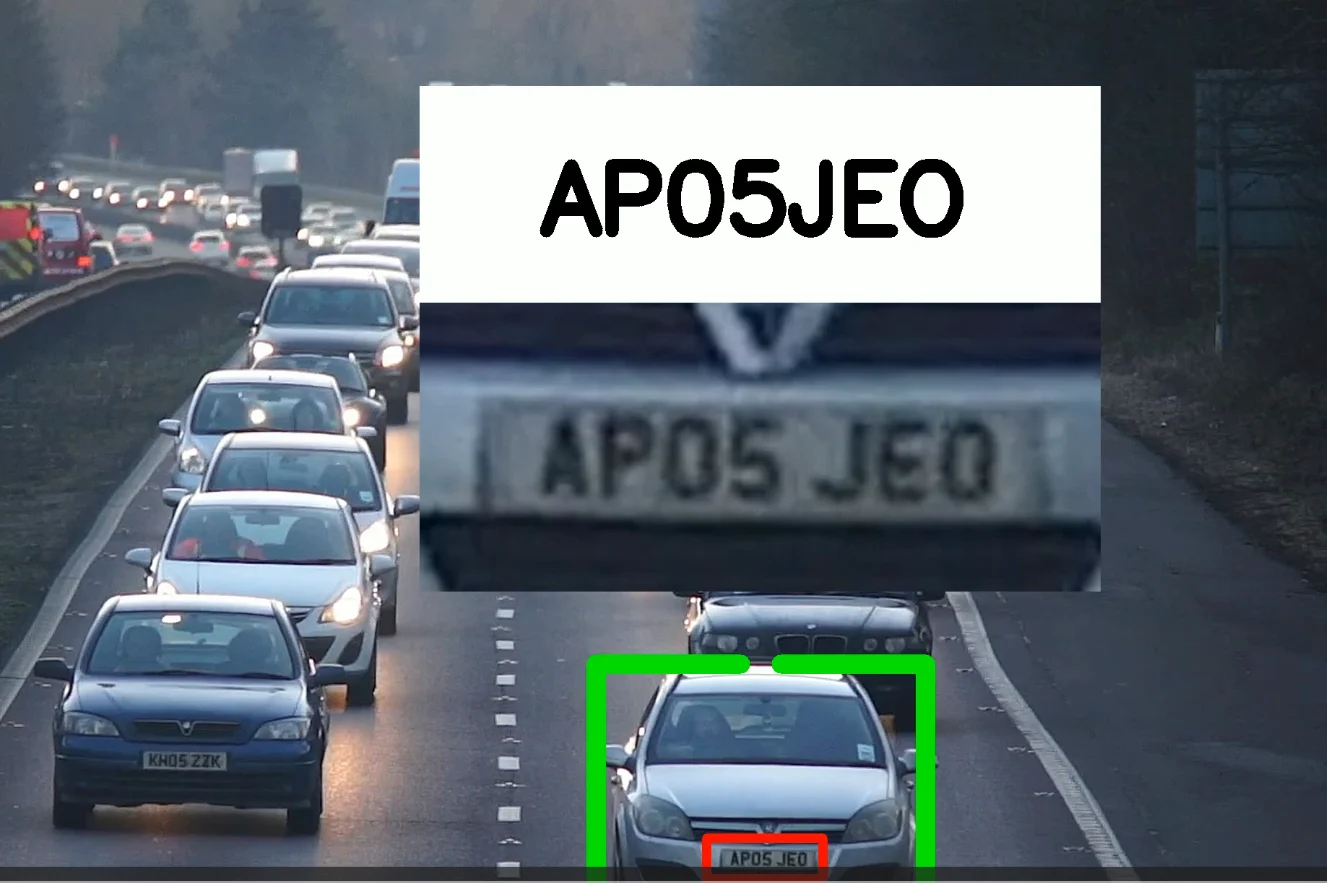
A production serving layer for computer vision models: request batching, a queue that degrades predictably under load, GPU memory management, and model versioning so you can roll a new checkout forward without downtime. Built around YOLO detection but model-agnostic.
What is inside
- Dynamic request batching with a configurable latency budget
- Bounded queue with predictable backpressure instead of unbounded memory growth
- GPU memory management and warm-up on startup to avoid first-request latency spikes
- Model versioning with zero-downtime rollout and instant rollback
- Prometheus metrics for latency percentiles, queue depth and GPU utilisation
- Works with YOLO out of the box, and any PyTorch model with one adapter
Built with
- Python
- PyTorch
- FastAPI
- YOLO
- Docker
- Prometheus
Next step
Have an AI problem worth solving?
Tell me what you are trying to build. I will tell you honestly whether AI is the right tool, what it would take, and how I would approach it.
Typical reply within 24 hours
Working from Dhaka, Bangladesh · remote worldwide